 Melta
Blog
One brief, three builds: three agent setups compared
We wrote one concept and had it built three times, with an identical brief and an identical model. Only the agent setup changed. Here are all the measurements, the three finished shops, and what we learned from it for the default setting.
The setup
Every build on Melta starts with a concept. For this comparison we generated it exactly once, from a short idea: an online shop for numbered collector's ducks made of emerald glass, with a catalogue, editions, cart, checkout, customer account, certificate download, newsletter and an admin area. The finished concept is 33,293 characters long and carries the full technical build plan next to the customer-facing part.
That one document went into the build three times as the brief, word for word the same. Each time the builder was Claude Opus 5 running in Claude Code, in its own isolated container, with the same tools, the same platform modules and the same checks. We changed only two switches:
- Multi-agent on, effort medium. The agent may fan the work out to subagents and has to run its own review pass before finishing, in which separate agents go through the product critically. Effort medium is what Claude Code sets as the default on a subscription since spring 2026.
- Multi-agent off, effort medium. One agent does everything itself, no subagents, no review pass.
- Multi-agent off, effort high. Like variant two, with the reasoning effort explicitly set to high.
All three ran on 4 and 5 September 2026, each until the build reached the preview. On Melta the preview is filled automatically with demo data, three test logins and a catalogue of eight items.
The numbers
| Multi-agent, medium | Single agent, medium | Single agent, high | |
|---|---|---|---|
| Time to preview | 140 min | 92 min | 110 min |
| Output tokens in total | 1.07 million | 380,000 | 333,000 |
| of which subagents | 786,000 | 0 | 0 |
| Cache reads | 105 million | 90 million | 58 million |
| Cost at API list prices | 102 USD | 59 USD | 44 USD |
| Cost, relative | 2.3 times | 1.35 times | 1 time |
Cost is the value of the tokens at the API list prices of Claude Opus 5, that is 5 USD per million input tokens, 25 USD per million output tokens, 6.25 USD per million cache writes and 0.50 USD per million cache reads, plus the generated images. The ratio refers to the cheapest variant. The tokens come from Claude Code's telemetry, split into main run and subagents, not from an estimate.
Two things stand out immediately. The multi-agent variant produced more than twice the output tokens, three quarters of them in subagents, and it took the longest. And the variant at effort high has fewer cache reads than the same variant at medium: it searched less and thought more, which made it the cheapest of the three.
The three shops
All three run as public previews with demo data and a demo bar. Purchases go through a test payment account; the test card 4242 4242 4242 4242 works at checkout. Each shop is what its run delivered, with catalogue, editions, cart, checkout, customer account and admin area.
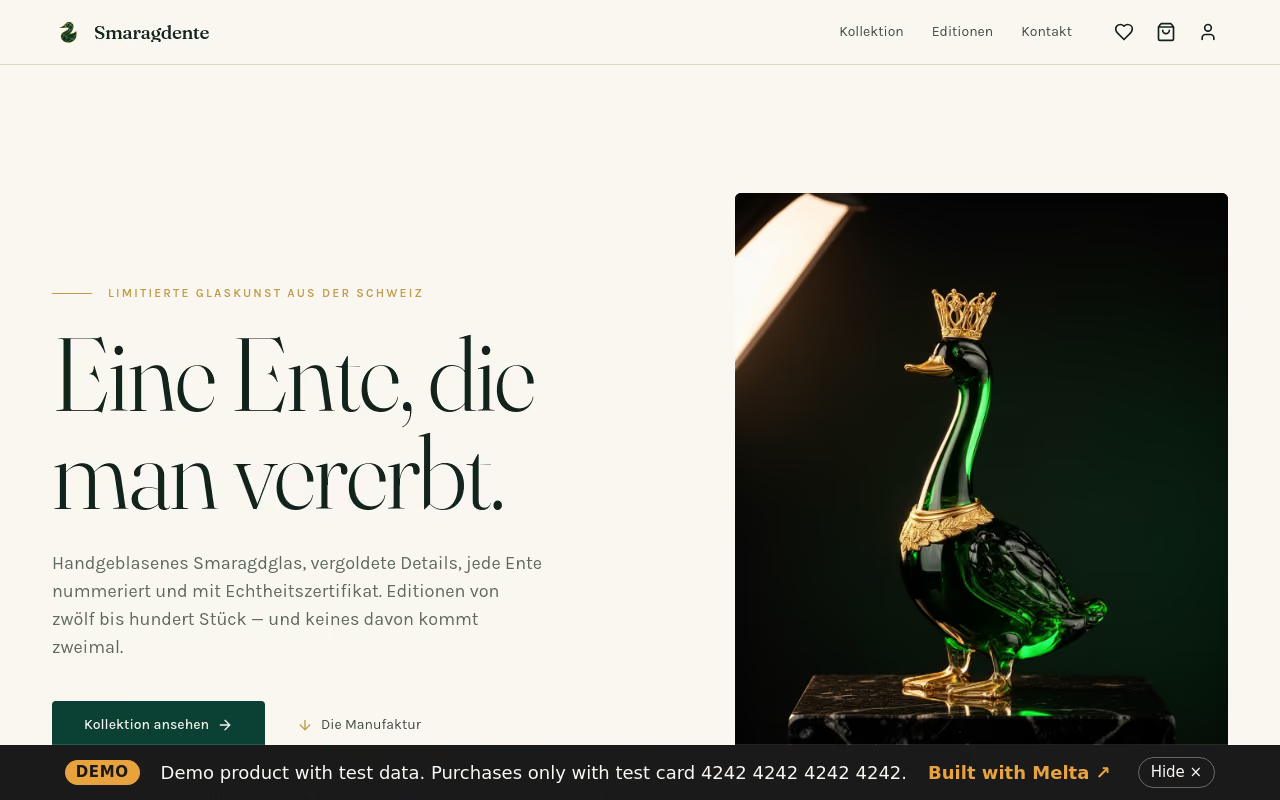
Multi-agent, medium: the shop from the first setup.
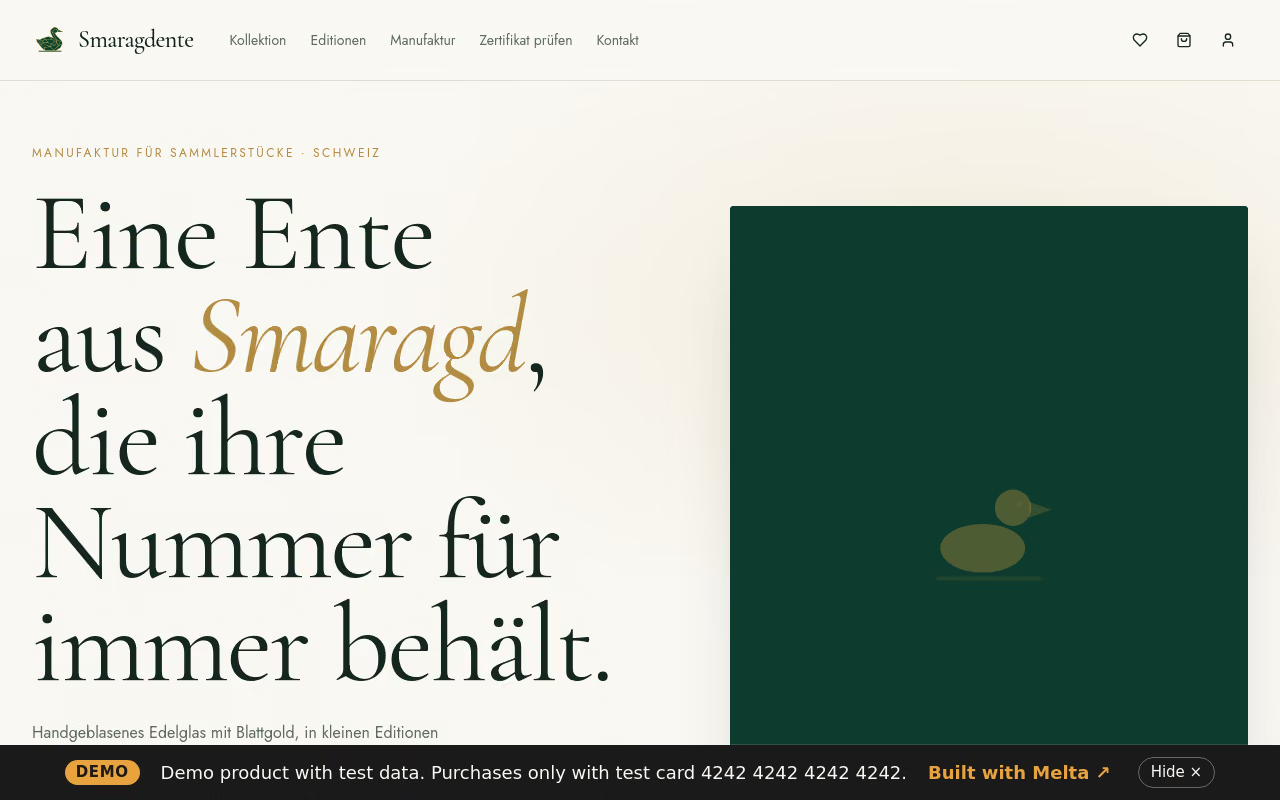
Single agent, medium: the shop from the second setup.
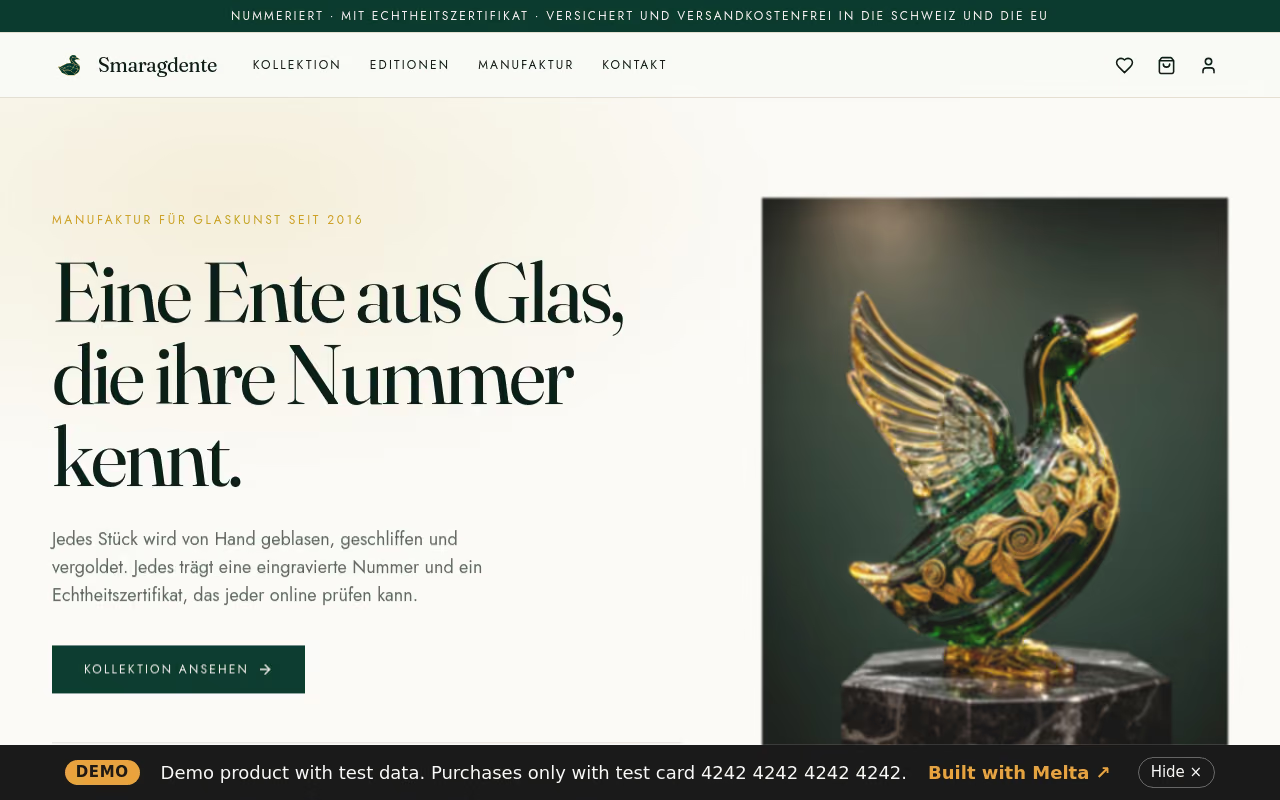
Single agent, high: the shop from the third setup.
What we take from it
One data point is not proof, and we will repeat the experiment with other concepts and with the next models. Two things we take with us already:
- The reasoning effort is a quality lever, not just a cost lever. The build at high was cheaper than the one at medium because it searched less. Since this comparison, Melta sets effort high as the default for every full build.
- More agents means more tokens and more time. The review pass with separate agents costs about twice as much. It stays switched on at Melta because it is the more thorough variant. Whoever flips the switch in the operator menu gets the cheaper one.
Topics: Benchmark, Agents, Building
Describe your product - Melta does the rest.
A concept uses only a few credits. It is built, put online and operated once you approve it.
Get early access